
Why Pay for Long Reasoning When Rewrite Do Trick? Causal Effects of Reasoning History Compaction on Future Generation and Agent Cost


Abstract
Rewriting reasoning histories into compact state records reduces future reasoning length and token costs in open-weight models without retraining.
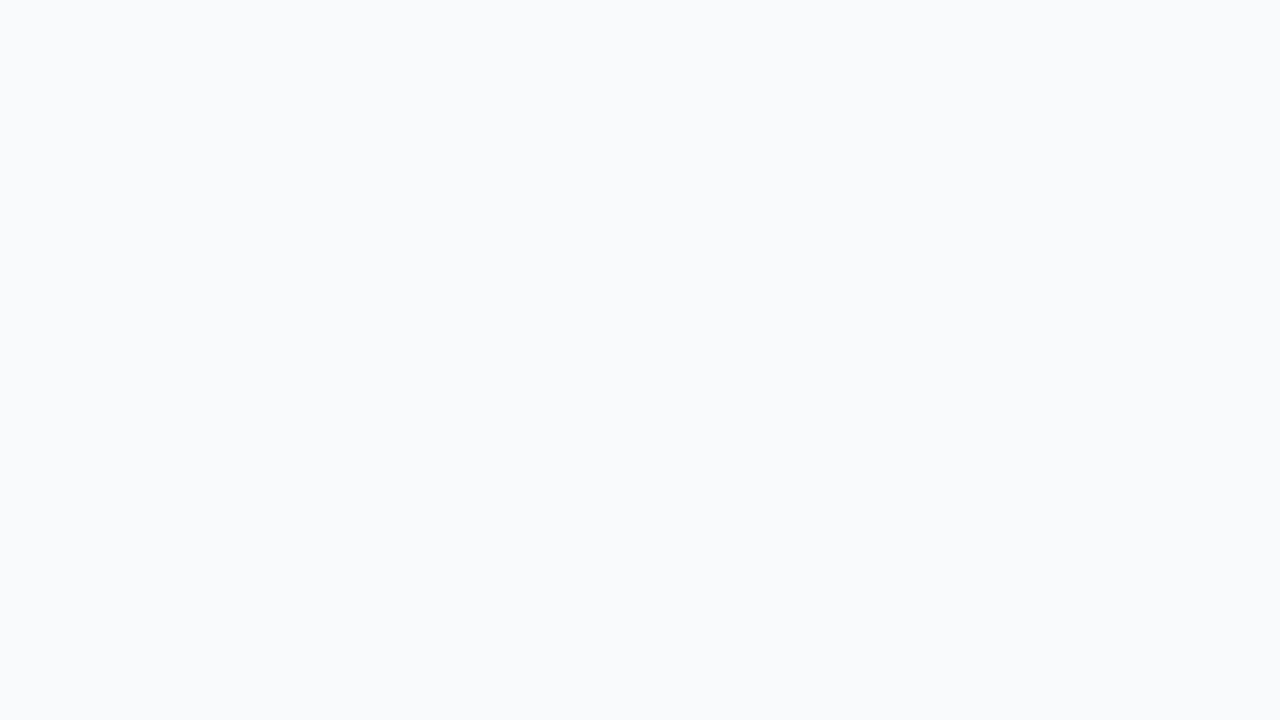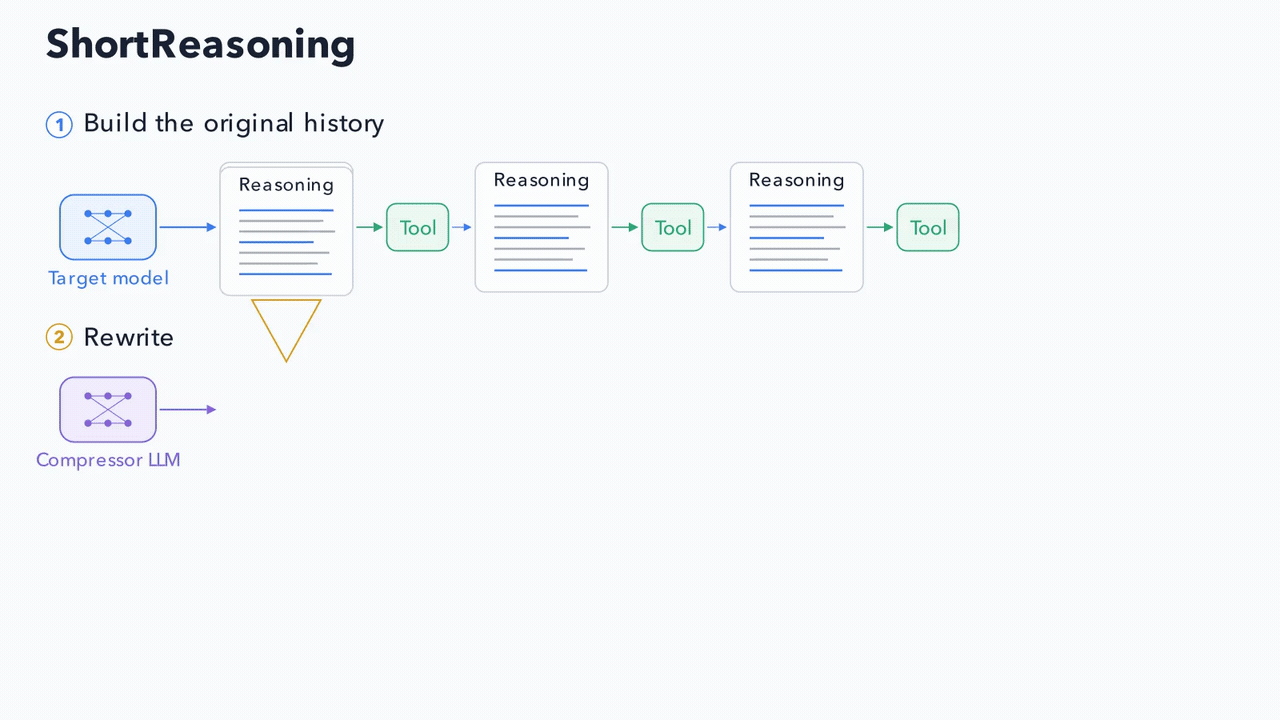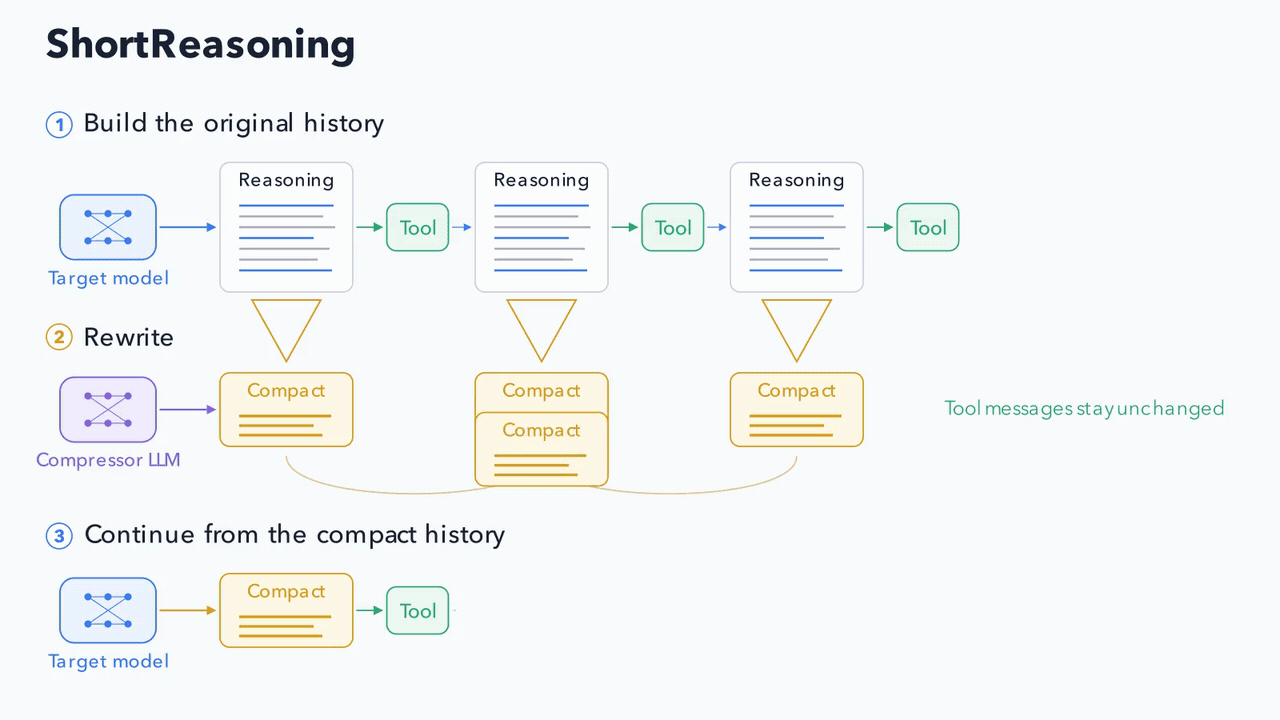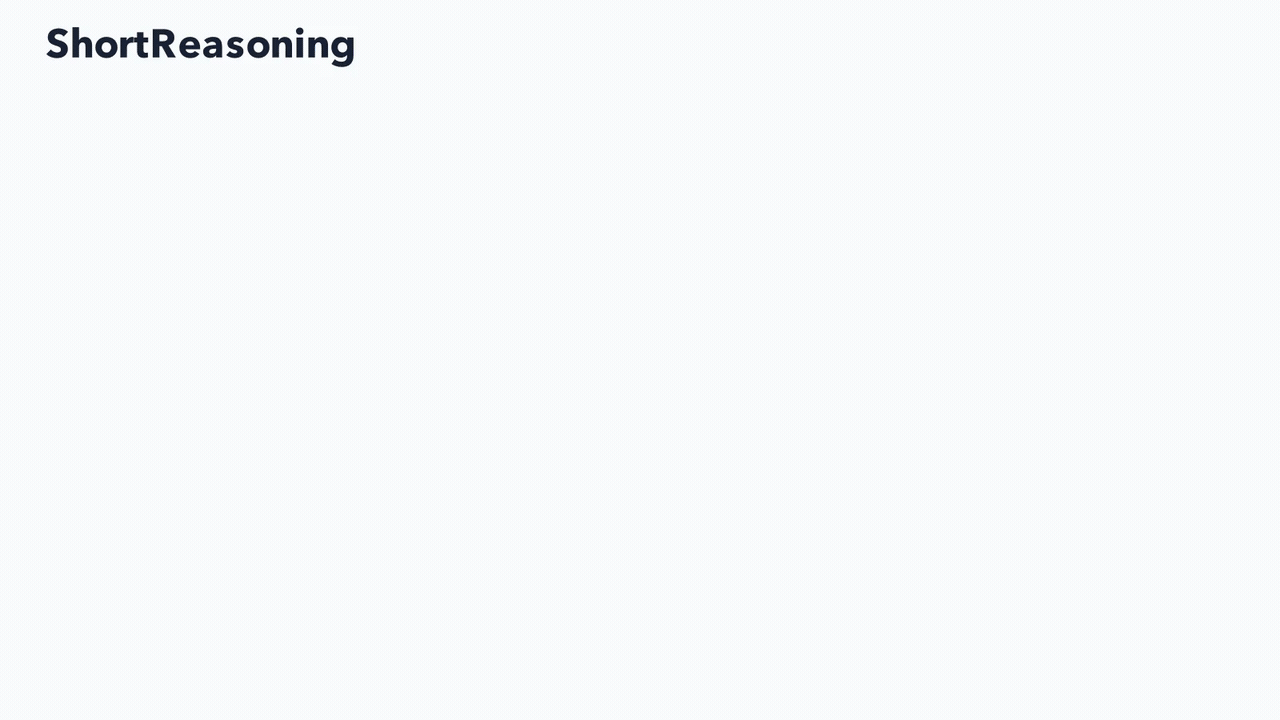
Reasoning substantially improves language models' ability to solve difficult problems, but long reasoning traces make these gains expensive. Efficient reasoning should express useful analysis in fewer tokens by reducing repetition and text that adds little value to solving the problem. Progress in proprietary models motivates this goal, yet their hidden scratchpads limit direct study of how it is achieved. We investigate whether open-weight models can generate less verbose reasoning by changing the form of their own earlier thoughts, without retraining. Our intervention rewrites prior reasoning into compact state records before pending tool results are revealed, then compares continuations from original and compact histories. Across the tested models, accepted compact histories usually shorten future reasoning; a coding case study also shows less repeated verification after a shared candidate solution. In software-agent deployments, compaction can reduce total spending, although task quality and rewrite-inclusive time depend on the target and compressor. These findings identify reasoning history as one way to reduce future reasoning-token use and motivate model-specific compaction policies evaluated for both efficiency and retained capability.
Community
ShortReasoning
In ShortReasoning, I show that rewriting a model’s earlier reasoning into compact state can shorten its newly generated reasoning without retraining.
In the coding-agent case study, MiniMax M3 with external compaction cost 34% less and used 59% less summed model-request time, including rewrite overhead.
(all “frontier” open models from july 2026 were tested - DeepSeek, Nemotron, GLM, Kimi, MiniMax and all on average produce shorter reasoning)
I built a simple compactor, but there is plenty anyone can play with:
- Which model compacts: a specialist fine-tune, a smaller cheaper model, or a fast “System 1”-style model. Classifiers could help select what to keep.
- What context it gets: one reasoning block, or more of the task and history?
- How much it compacts: individual blocks, many-to-many rewrites, or many-to-one summaries.
- How faithfully: aim to preserve information, as I did, or summarize only the most important parts.
- How inference is scheduled: run compression asynchronously alongside tool execution to potentially hide some rewrite latency.
Broader takeaway
Across all six tested routes, accepted compact histories led to shorter median continuations. My bet is that the capability is already there across most, perhaps all, current open-weight reasoning models. We should incentivize future generations to use it, expressing useful analysis in fewer tokens while keeping their problem-solving ability.
This method can already generate compact traces for simple self-distillation. The compressor can be the model itself, or potentially a weaker model, since rewriting may be easier than solving the original task.

This is an automated message from the Librarian Bot. I found the following papers similar to this paper.
The following papers were recommended by the Semantic Scholar API
- RCCM: Diagnosing Gains and Harms in Reasoning-Prompt Transfer (2026)
- Compact-Bench: Measuring What Context Compaction Costs Long-Horizon Coding Agents (2026)
- Truncated Reasoning Under a Budget: Evaluating System-1 Models as Decision-Makers (2026)
- VETR: Execution-Grounded Self-Improving Agent for Symbolic Graphics Reasoning (2026)
- REA: From Correct LLM Judgments to Safe Decision Delivery (2026)
- Visible Reasoning Is Not a Universal Optimizer: Persona- and Thinking-Dependent Effects in Analytics Code Generation (2026)
- Selective Reasoning for Typed Decision Models: When to Start, Read, and Stop (2026)
Please give a thumbs up to this comment if you found it helpful!
If you want recommendations for any Paper on Hugging Face checkout this Space
You can directly ask Librarian Bot for paper recommendations by tagging it in a comment: @librarian-bot recommend
Get this paper in your agent:
hf papers read 2611.03852 Don't have the latest CLI?
curl -LsSf https://hf.co/cli/install.sh | bash Models citing this paper 0
No model linking this paper
Datasets citing this paper 0
No dataset linking this paper
Spaces citing this paper 0
No Space linking this paper
Collections including this paper 0
No Collection including this paper