

sanoTTS — a tiny neural voice that runs anywhere
Release status: Ready for release.
sano (सानो) — Nepali for "small." A family of tiny neural text-to-speech voices — 294k to 2.27M parameters — that run with no cloud and no NPU: real-time on a ~$3 ESP32-S3 (out a GPIO into an LM386 and a speaker), or live in the browser via WASM.
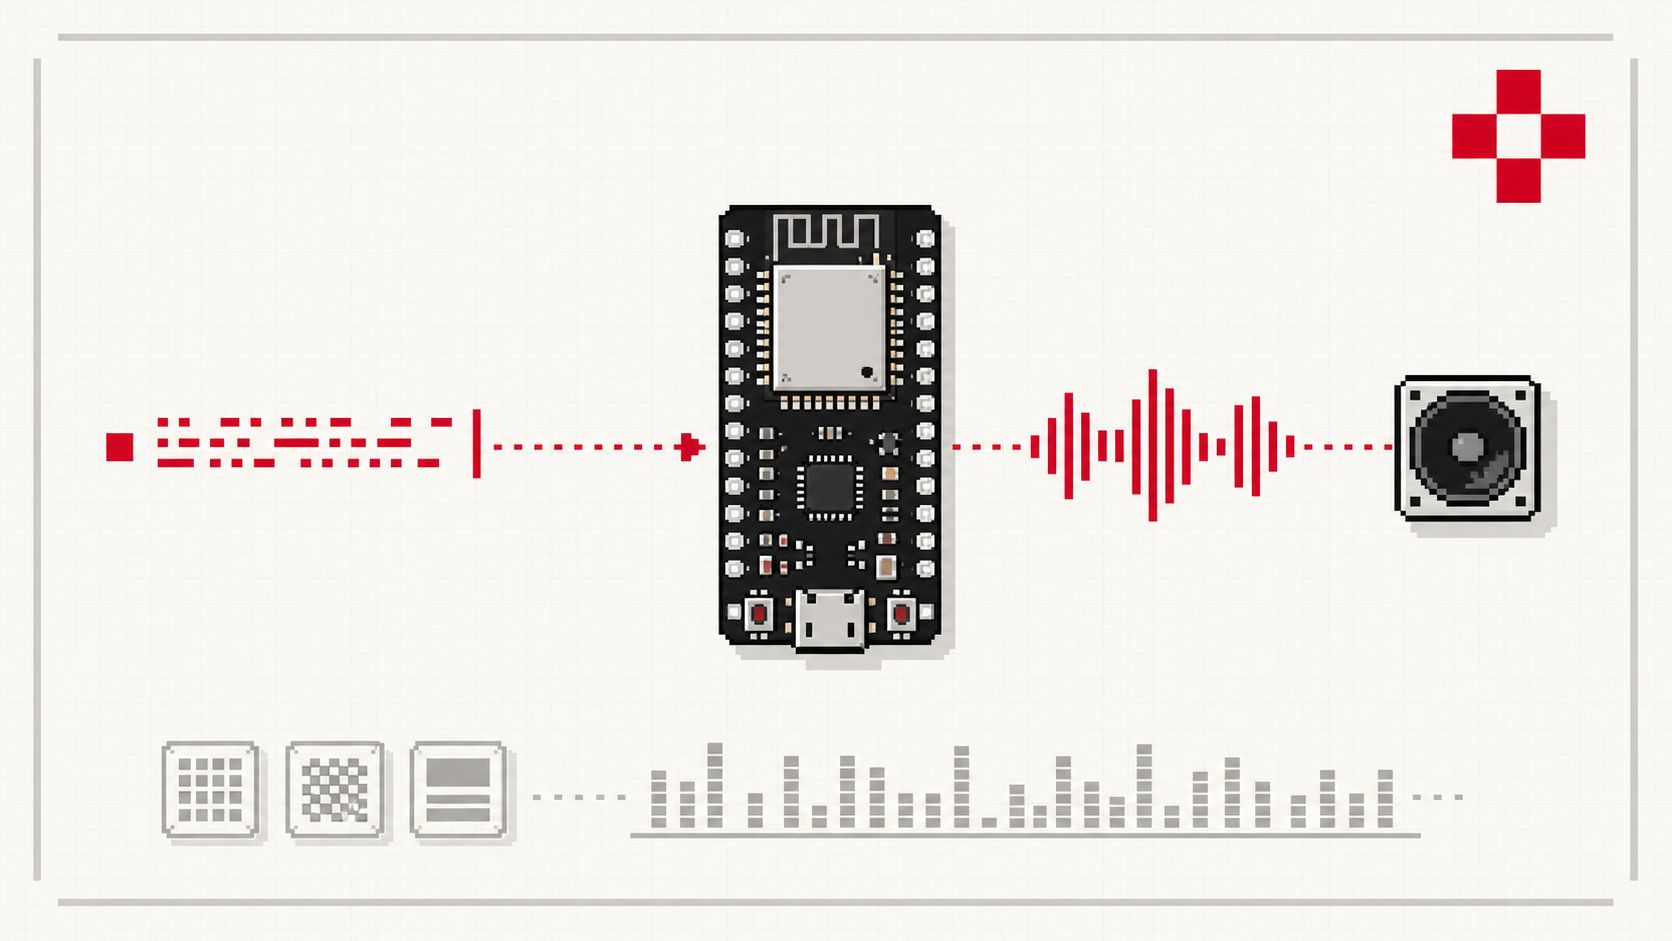
| Parameter range | 294,279 – 2,272,145 |
| Runs real-time on a $3 microcontroller | ESP32-S3, out a GPIO into an LM386 |
| Runs in the browser | WebAssembly, no server |
| Per-voice footprint | 337 KB to 8.7 MB, zero dependencies (espeak-ng phonemizer included) |
| Live browser demo | 31 voices across 17 languages — English, Nepali (नेपाली), Hindi (हिन्दी), Vietnamese (Tiếng Việt), Indonesian (Bahasa), Chinese (中文), German, French, Spanish, Italian, Portuguese, Russian, Czech, Romanian, Turkish, Arabic, and Polish |
| License | open source, GPL-3.0 |
Live demo: tts.ampixa.com/sanoTTS — 31 voices across 17 languages, synthesizing your text live in the browser, no server, no upload.
The count is the live demo's voice-picker inventory, including separate model sizes for the same language. Polish is currently demo-only: its weights are not yet hosted in this Hugging Face repository. The repository also retains the older Chinese voice for compatibility; the live picker uses its Chinese Xiaoya replacement.
Download
Both packages stream their weights from this repo by default.
import sanotts
sanotts.synthesize("Hello world", voice="heart")     # downloads heart/ from here
import { SanoTTS } from 'sanotts-web';               // fetches web/voices/ from here
const tts = await SanoTTS.load();
const result = await tts.synthesize('Hello world', { voice: 'heart' });
Python needs sanotts >= 0.3.0, the browser sanotts-web >= 0.3.0. Both fall
back to the GitHub releases or the Pages host if Hugging Face cannot be
reached, so an outage here cannot break an install. Python packages land in
~/.cache/sanotts/; set SANOTTS_VOICE_SOURCE=hf or =github to pin one
host. In the browser, passing voiceBase yourself turns the fallback off, so
a self-hosted deployment never quietly reaches back to our servers.
Samples
Selected samples are embedded below; this is not the full 31-voice demo inventory.
"Package here" links to a voice's Python/C package when available. Browser
bundles for Nepali, Hindi, and Chinese are also hosted here under web/voices/.
The older Chinese sample below is retained for compatibility; the live demo
uses Chinese Xiaoya.
The browser collection additionally includes German, French, Spanish, Italian, Portuguese, Russian, Czech, Romanian, Turkish, Arabic, and the experimental English Trellis voice. Browse the browser bundles and try all 31 voices, including demo-only Polish, in the live demo.
| Voice | Language | Params | SCOREQ | Package here | Sample |
|---|---|---|---|---|---|
| heart | English 🇺🇸 | 2.27 M | 3.48 | heart/ |
|
| hfc | English 🇺🇸 | 1.83 M | 3.94 | hfc-en-1p8m/ |
|
| amy | English 🇺🇸 | 1.46 M | 4.13 | amy-en-1p46m/ |
|
| kristin | English 🇺🇸 | 1.40 M | 4.09 | kristin-en-1p4m/ |
|
| amy-small | English 🇺🇸 | 1.08 M | 3.70 | amy-en-1p1m/ |
|
| robot (on-device, int8) | English 🇺🇸 | 567 k | — | not packaged here (int8 MCU format) | |
| heart-nano | English 🇺🇸 | 294 k | 2.29 | heartnano/ |
|
| Indonesian | Bahasa | 1.46 M | — | id-newstts-1p46m/ |
|
| Vietnamese | Tiếng Việt | 1.46 M | — | vi-vais1000-1p46m/ |
|
| Nepali | नेपाली | 1.47 M | — | browser bundle | |
| Hindi | हिन्दी | 1.50 M | — | browser bundle | |
| Chinese | 中文 | 1.50 M | — | browser bundle |
SCOREQ is a no-reference naturalness predictor, higher is better; it is only reported for the English voices, which share one 24-sentence eval set. The other languages haven't been scored against a comparable reference yet.
Size does not order this table, and we are not going to pretend it does.
amy at 1.46M scores higher than heart at 2.27M because they come from
different teachers and different architectures, not because one is bigger.
amy and the voices above it are the piperlite lineage, distilled from a
Piper/VITS teacher at 22.05 kHz. heart and heart-nano are the newer
nano lineage — 24 kHz, mel-100 → ConvNeXt1D → iSTFT, distilled from a
Kokoro teacher through a frozen Vocos — which is the one that quantizes to
int8 and runs on a microcontroller. The two are not interchangeable and the
sanotts package picks the right runtime for you.
The heart and heart-nano scores were re-measured on 2026-09-04; the eval
set, checkpoint hashes, exact commands and all 24 per-clip scores are in
evidence/heart-diverse24-remeasure-20260904.json.
They were scored on the float32 reference render. The shipped heart-nano
int8 export tracks that render at 0.981 waveform correlation, and heart
ships as float32 because its int8 export reached only 0.951 against a 0.98
gate.
The "robot" row is the 567,008-parameter model that runs on the ESP32-S3.
Install & use
| Platform | Install | Then |
|---|---|---|
| Python | pip install sanotts |
sanotts say "Hello" --voice heart -o hello.wav |
| Web (npm) | npm install sanotts-web |
const tts = await SanoTTS.load(); await tts.synthesize('Hello', {voice:'heart'}) |
| Web (no build) | copy dist/ + voices/ |
see Deploy on your own site in the GitHub README |
| Arduino / PlatformIO | zip-install or lib_deps = https://github.com/Ampixa/sanoTTS.git |
arduino/README.md |
| Hugging Face | this repo | the voice packages above, downloaded for you by pip install sanotts |
| Browser | nothing | tts.ampixa.com/sanoTTS |
Pip voices: heart, hfc, amy-1p8m, amy, kristin, vi, id,
amy-1p1m, heart-nano. Pure numpy inference, no torch, no onnxruntime.
Streaming and the Open TTS Leaderboard
sanotts streams: Synthesizer.synthesize_stream(text) yields audio chunk by
chunk, and the chunks join to exactly what synthesize() returns, up to
float32 rounding.
from sanotts import Synthesizer
syn = Synthesizer("heart-nano")
for chunk in syn.synthesize_stream("Hello from a 294k-parameter voice."):
    ...  # float32 at syn.sample_rate, ready to play
The three English voices were evaluated by the maintainers of the
Open TTS Leaderboard
on HF Jobs (PR #53, sanotts 0.5.4).
Time to first audio is measured on CPU (cpu-upgrade, one thread, batch size 1)
over the 497 CV3-Eval English prompts; RTFx is the main eval's throughput, run
on one CPU thread. WER is from Qwen3-ASR over Seed-TTS, CV3-Eval and MiniMax English.
| Voice | Params | TTFA p50 | TTFA p95 | RTFx | WER | UTMOS |
|---|---|---|---|---|---|---|
| heart-nano | 294 k | 2.8 ms | 5.9 ms | 214 | 1.07 % | 2.39 |
| heart | 2.27 M | 6.4 ms | 9.8 ms | 49 | 0.86 % | 3.30 |
| amy | 1.46 M | 22.7 ms | 36.3 ms | 15 | 1.12 % | 3.99 |
On that board, larger and newer models score higher on UTMOS than these voices do; what sanoTTS brings is the latency, the throughput and the size.
How it stacks up
Open small-scale TTS on an honest gate — a diverse 24-sentence set scored with the same no-reference suite (SCOREQ / UTMOS are naturalness predictors, DNSMOS-SIG is signal quality; higher is better). Parameter counts are inference-time and exclude the shared external G2P.
| System | Params | SCOREQ | UTMOS | DNS-SIG |
|---|---|---|---|---|
| sanoTTS (amy) | 1.46 M | 4.13 | 4.10 | 3.61 |
| TinyTTS | 1.62 M | 3.94 | 3.65 | 3.62 |
| Inflect Nano | 4.63 M | 3.81 | 3.65 | 3.58 |
| Kitten TTS nano | 15 M | 3.02 | 3.58 | 3.43 |
| Piper (our teacher) | ~15 M | 4.71 | 4.47 | 3.65 |
| Kokoro | 82 M | 4.89 | 4.52 | 3.69 |
Among the systems in this table, sanoTTS amy is the smallest and scores
highest on naturalness (SCOREQ and UTMOS) below Piper — beating TinyTTS
while being smaller. This is our own 24-sentence comparison; on the Open TTS
Leaderboard's larger sets, several small models (for example Paradee-8M and
PiVo-1.4M) have higher UTMOS than amy. On DNSMOS-SIG, TinyTTS edges us by 0.01 — no single
metric tells the whole story. It's the only one that runs a full neural
stack on a $3 MCU. The frontier only pulls ahead at Piper, the ~15M teacher
we distilled from, and Kokoro (82M, 56× larger) — a gap we don't claim to
close. Reproduce it with tools/eval_mos_all.py + tools/eval_scorecard.py
in the GitHub repo.
Shipped-file sizes: sanoTTS amy 2.8 MB fp16 and TinyTTS 3.5 MB fp16, both verified from the released files; Kokoro's ~330 MB fp32 is its widely cited public figure.
How it works
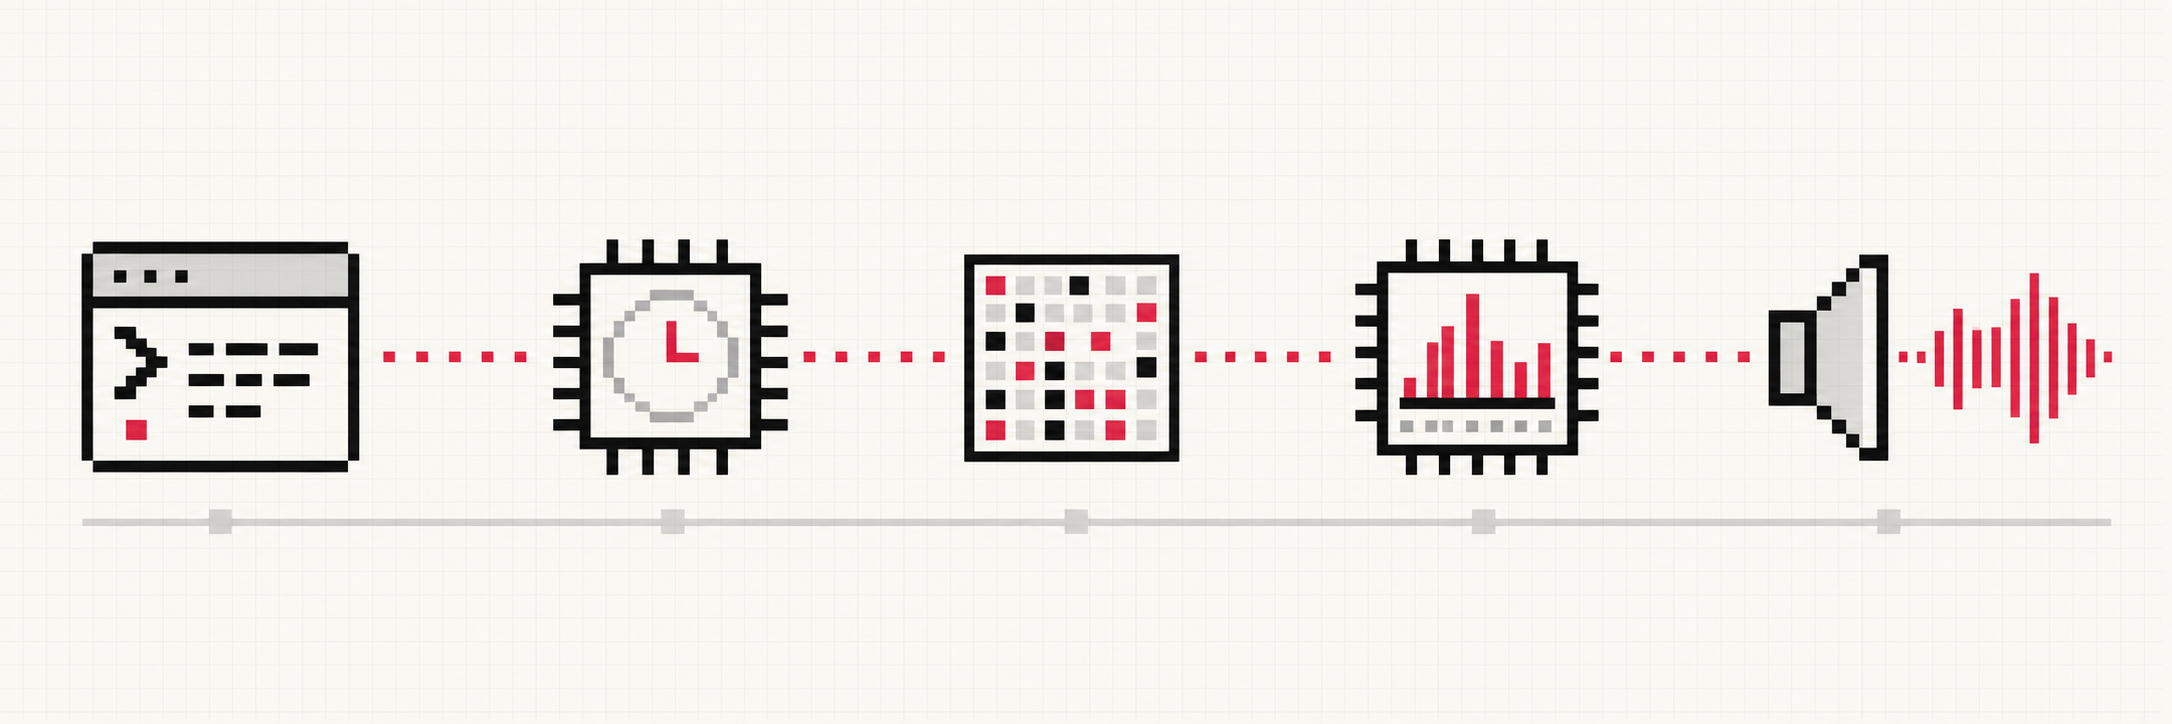
espeak-ng provides phoneme IDs; a duration model predicts timing; an
acoustic model predicts generator latents; a decoder renders audio. The
piperlite voices (amy, kristin, hfc, and the other languages) use a compact
time-domain decoder running in fp32 at 22.05 kHz. The nano voices (heart,
heart-nano) and the 567,008-parameter on-device model use an iSTFT decoder
at 24 kHz, quantized to int8 where it has to fit and run in real time on the
ESP32-S3. Models are distilled from a Piper/VITS or Kokoro teacher — see
docs/distillation-recipe.md
in the GitHub repo for the full recipe.
Deploy
- ESP32-S3 talking device — a standalone WiFi dashboard: type text, the
board phonemizes (on-chip espeak-ng) and speaks. See
mcu/ports/esp32s3/. Board-by-board measurements are inBOARDS.md; the silicon figures there are for theen_us_e12nanolineage, which is a sibling ofheart-nano, not the same weights. - Browser — the full stack in WASM, no server. ▶ Hear and synthesize
all 31 voices across 17 languages live; source in
web/. - Other MCUs — which chips can run it and how well:
docs/mcu-classes-and-porting.md.
Links
- Source, recipes, eval tooling: github.com/Ampixa/sanoTTS
- Live browser demo: tts.ampixa.com/sanoTTS
- npm package: sanotts-web
- PyPI package: sanotts
License
GPLv3 — see LICENSE.
The pipeline builds on GPLv3 components (notably
espeak-ng for G2P, and
piper), so the project as a
whole is GPLv3.
Copyright (C) 2026 Ampixa.
Files here
Two package layouts, because there are two graphs.
piperlite (amy-en-1p46m/, kristin-en-1p4m/, hfc-en-1p8m/,
amy-en-1p1m/, id-newstts-1p46m/, vi-vais1000-1p46m/) — a flat fp16
blob addressed by manifest offsets:
manifest.json                 weights.fp16.bin
piper-phoneme-config.json     (+ sibilant-injection calibration where applicable)
nano (heart/, heartnano/) — the mel-100 stack, two blobs plus the
generated offset header:
meta.json          lineage, per-file sha256, sample rate, vocab
front_*.bin        duration + acoustic
model_*.bin        decoder
nano_q8_meta.h     tensor offsets
heartnano/ ships *_q8.bin (int8, 345,232 bytes total); heart/ ships
*_f32.bin (float32, 9,137,920 bytes) because its int8 export missed the
fidelity gate. Both layouts are consumed by the sanotts Python package and
the portable C runtime.
web/voices/ is a third thing and exists for the browser. The piperlite
voices ship there as front_f32.bin + dec_f32.bin, a different artifact
from the weights.fp16.bin the Python package reads, which is why the same
voice appears twice in this repo under two names. It mirrors web/ in the
GitHub repo byte for byte and is what sanotts-web fetches. The nano voices
are not duplicated: web/voices/heart/ and heart/ hold the same blobs.
samples/ holds the audio clips embedded above (mp3, one or two per voice,
plus the on-device mcu-567k.mp3), and evidence/ the eval report behind the
heart scores.
- Downloads last month
- 579,953
32-bit