

Xevn-4B
Xevn is a 4B decision model built for Korean, trained for Korean understanding, knowledge, and judgment.
Xevn follows the Jev decision format. It reads a question and its options once and returns the answer together with a probability for every option. There is no text generation, so a request costs one forward pass.
Model overview
- Type: Decision model with one forward pass per question and no text generation
- Parameters: 4B
- Architecture: Hybrid Gated DeltaNet and attention, 32 layers (24 Gated DeltaNet, 8 full attention)
- Hidden size / vocabulary: 2,560 / 248,320
- Question types:
choice,noul,score - Languages: Korean (primary), English
- Precision: bf16 (Transformers)
Quickstart
pip install -U torch "transformers>=5.2.0" huggingface_hub
hf download quevirus/Xevn-4B --local-dir Xevn-4B
import sys
sys.path.insert(0, "Xevn-4B")  # the repository ships the xevn_infer.py helper
from xevn_infer import Xevn

model = Xevn("Xevn-4B", device="cpu")  # or "mps" on Apple silicon, "cuda" on NVIDIA
state = "고객: 어제 주문한 이어폰 값이 카드에서 두 번 결제됐어요. 오늘 안에 한 건 취소해 주세요."
# "Customer: the earphones I ordered yesterday were charged to my card twice. Please cancel one today."
questions = {
    "team": {"type": "choice", "instructions": "Which team should handle this ticket?",
             "criteria": {"billing": "Payments and refunds", "shipping": "Delivery", "account": "Login and account"}},
    "charged_twice": {"type": "noul", "instructions": "Was the customer charged more than once?"},
    "urgency": {"type": "score", "instructions": "How urgent is this ticket?",
                "criteria": ["Low", "Medium", "High"]},
}
result = model.request({"state": state, "questions": questions})
Output (rounded):
{
  "team": {"answer": "billing", "probs": {"billing": 0.998, "shipping": 0.001, "account": 0.001}},
  "charged_twice": {"answer": true, "probs": {"yes": 0.993, "no": 0.007}},
  "urgency": {"answer": 1.77, "probs": {"0": 0.041, "1": 0.150, "2": 0.809}}
}
From the command line, with the same request saved as JSON:
python Xevn-4B/xevn_infer.py --model Xevn-4B --request request.json
Transformers prints a notice when the optional flash-linear-attention and causal-conv1d kernels are not installed; the results are the same without them. For Apple silicon there are MLX weights, and for llama.cpp there are GGUF files.
Request format
A request is a state (text or any JSON value) and one or more named questions. Each question has a type, instructions, and criteria.
| Type | Use | criteria |
answer in the result |
|---|---|---|---|
choice |
Pick one of up to 26 options | {"key": "description", ...}, 2 to 26 options |
The key of the most probable option |
noul |
Yes or no | Optional {"true": "...", "false": "..."} |
true or false |
score |
Rate on a graded scale | ["lowest level", ..., "highest level"], 2 to 10 levels |
The expected level (0 is the first level) |
probs holds a probability for every option, yes/no, or level. For noul, a yes probability strictly between 0.2 and 0.8 is moved to 0.2 or 0.8 on the same side, so the model always commits to an answer. Readout temperatures per type are in temps.json (choice 1.1, noul 1.2, score 1.2).
Evaluation
Every model was run in 16-bit (bf16; Decider in its official FP16) with the same prompts and the same scoring, on an Apple M4 Max.
Scores are from our own runs with the same harness for every model. Headline = (Intelligence + Calibration) / 2, the JevBench score that combines accuracy and calibration. The best score in each row is bold; benchmarks where Xevn leads come first.
Korean
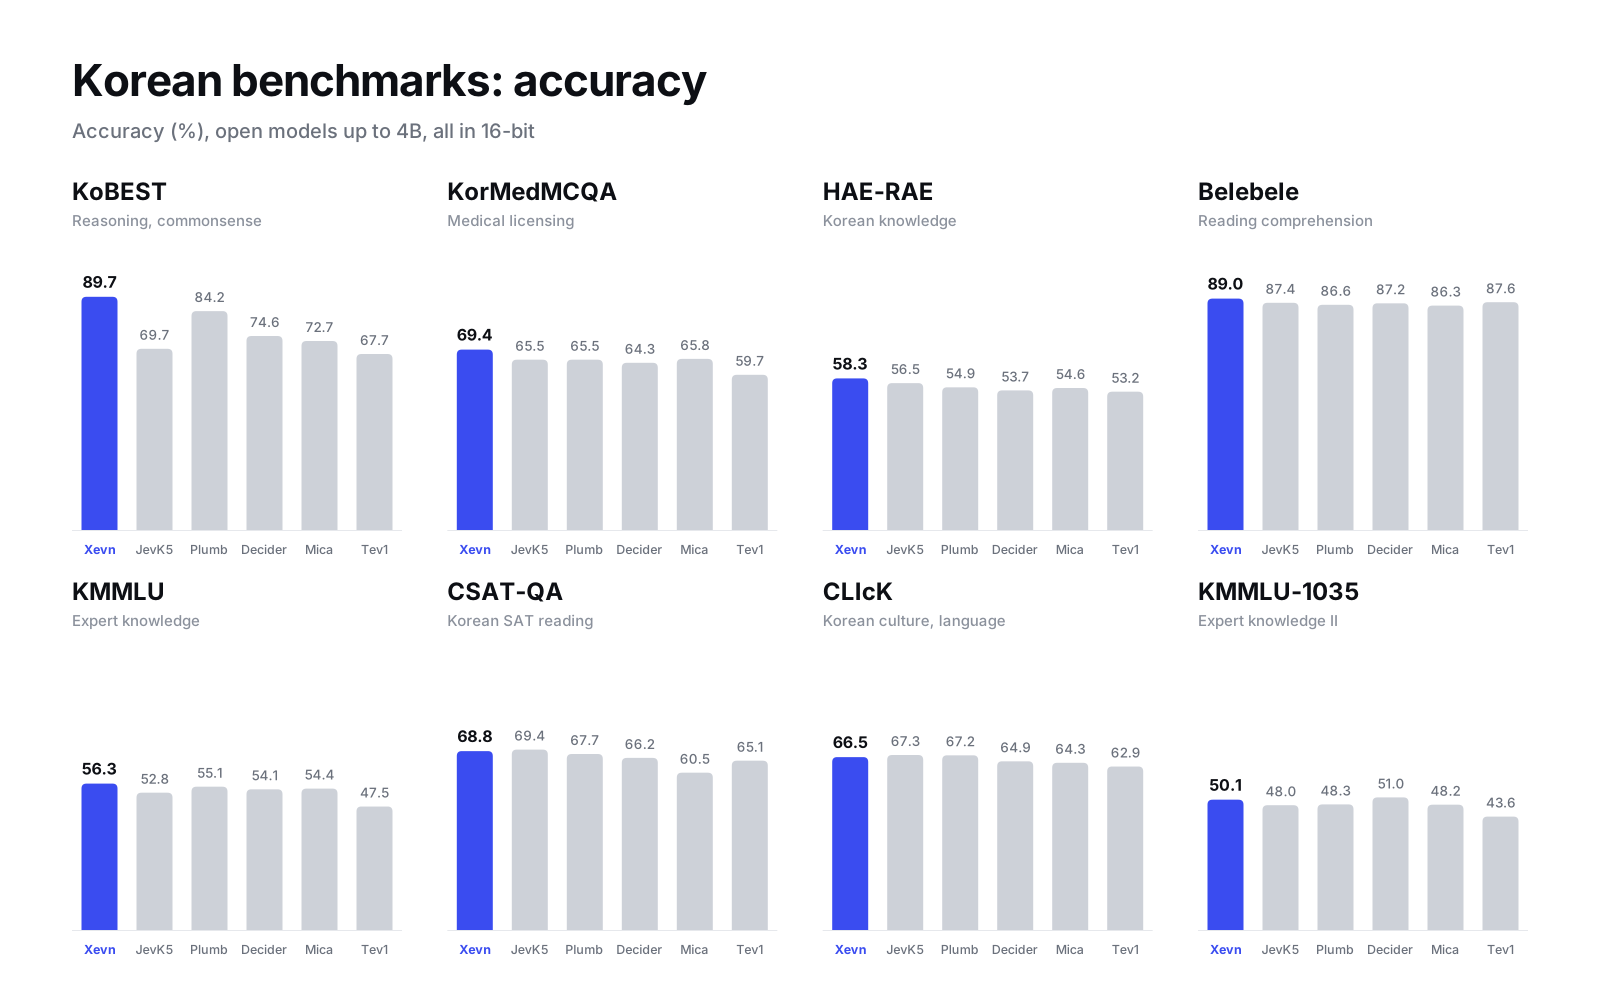
Accuracy (%)
| Benchmark | Measures | Xevn | JevK5 | Plumb | Decider | Mica | Tev1 |
|---|---|---|---|---|---|---|---|
| KoBEST | Reasoning and commonsense | 89.7 | 69.7 | 84.2 | 74.6 | 72.7 | 67.7 |
| KorMedMCQA | Korean medical licensing exams | 69.4 | 65.5 | 65.5 | 64.3 | 65.8 | 59.7 |
| HAE-RAE | Korean knowledge | 58.3 | 56.5 | 54.9 | 53.7 | 54.6 | 53.2 |
| Belebele | Reading comprehension | 89.0 | 87.4 | 86.6 | 87.2 | 86.3 | 87.6 |
| KMMLU | Expert knowledge across subjects | 56.3 | 52.8 | 55.1 | 54.1 | 54.4 | 47.5 |
| CSAT-QA | Korean SAT reading | 68.8 | 69.4 | 67.7 | 66.2 | 60.5 | 65.1 |
| CLIcK | Korean culture and language | 66.5 | 67.3 | 67.2 | 64.9 | 64.3 | 62.9 |
| KMMLU-1035 | Expert knowledge, second set | 50.1 | 48.0 | 48.3 | 51.0 | 48.2 | 43.6 |
Headline
| Benchmark | Xevn | JevK5 | Plumb | Decider | Mica | Tev1 |
|---|---|---|---|---|---|---|
| KoBEST | 92.0 | 83.7 | 84.2 | 82.0 | 85.3 | 87.1 |
| KorMedMCQA | 78.7 | 76.7 | 74.0 | 73.1 | 70.4 | 67.1 |
| HAE-RAE | 70.2 | 69.3 | 68.2 | 63.9 | 62.1 | 61.0 |
| Belebele | 90.3 | 89.7 | 87.7 | 89.3 | 86.4 | 89.2 |
| KMMLU | 68.5 | 63.3 | 67.8 | 58.1 | 58.5 | 55.3 |
| KMMLU-1035 | 60.1 | 55.7 | 57.8 | 53.3 | 49.5 | 49.3 |
| CSAT-QA | 76.4 | 76.6 | 77.3 | 72.3 | 65.7 | 74.4 |
| CLIcK | 72.5 | 74.8 | 73.1 | 68.5 | 68.1 | 68.6 |
English
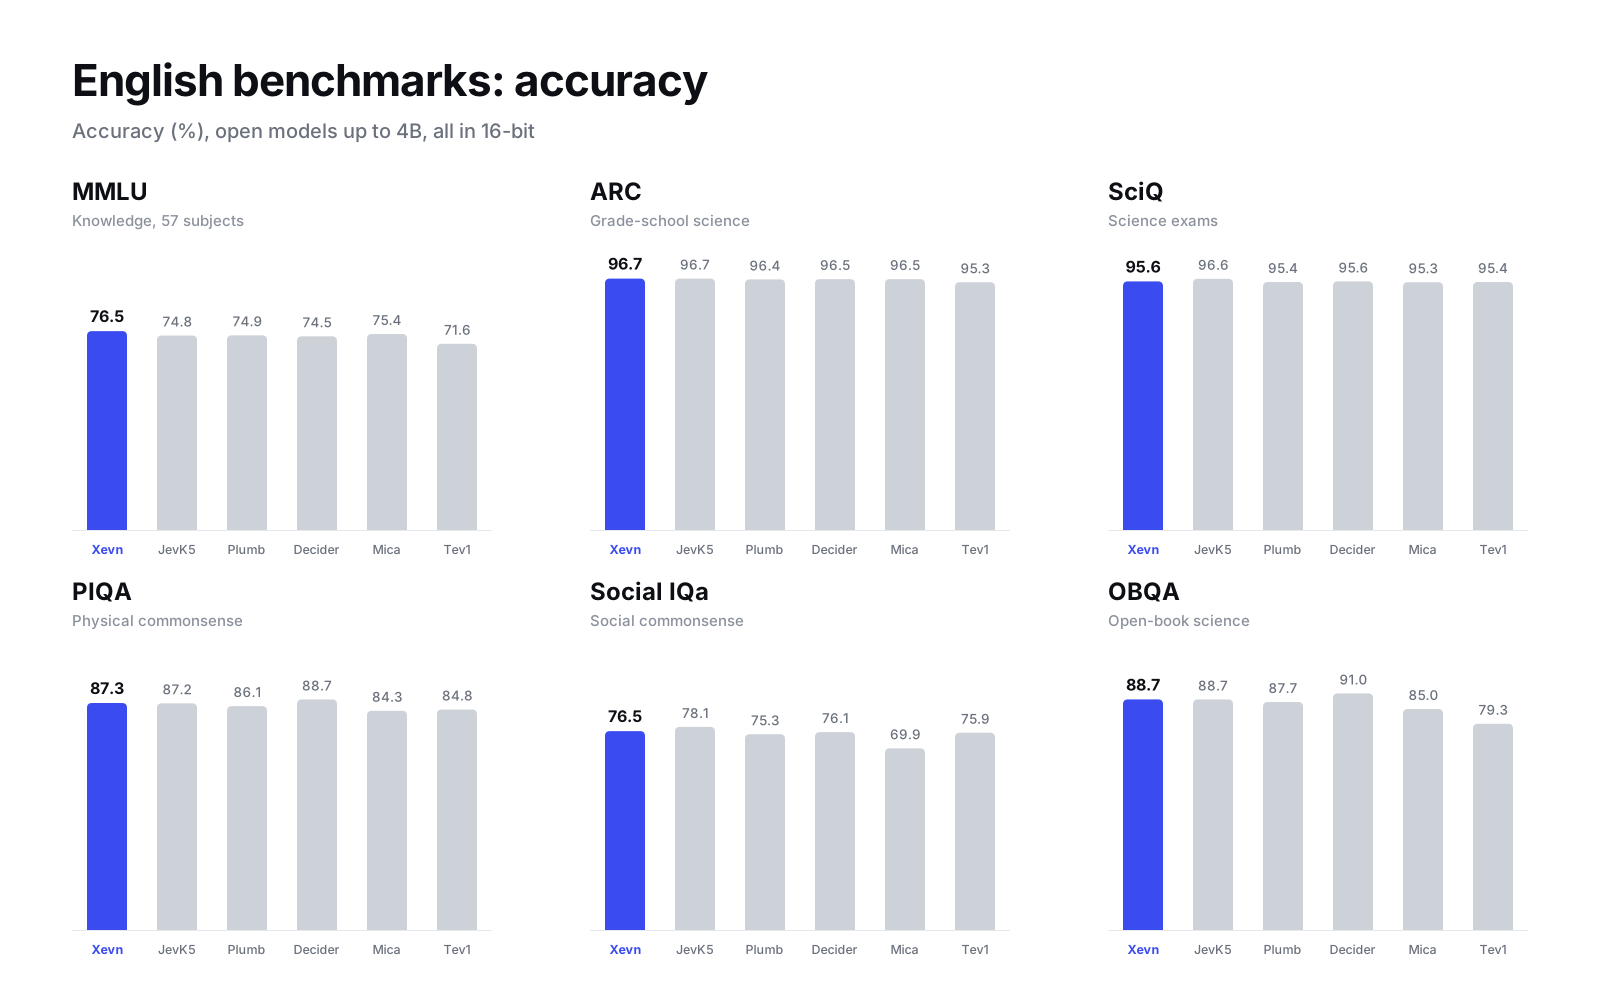
Accuracy (%)
| Benchmark | Measures | Xevn | JevK5 | Plumb | Decider | Mica | Tev1 |
|---|---|---|---|---|---|---|---|
| MMLU | Knowledge across 57 subjects | 76.5 | 74.8 | 74.9 | 74.5 | 75.4 | 71.6 |
| ARC | Grade-school science | 96.7 | 96.7 | 96.4 | 96.5 | 96.5 | 95.3 |
| SciQ | Science exam questions | 95.6 | 96.6 | 95.4 | 95.6 | 95.3 | 95.4 |
| PIQA | Physical commonsense | 87.3 | 87.2 | 86.1 | 88.7 | 84.3 | 84.8 |
| Social IQa | Social commonsense | 76.5 | 78.1 | 75.3 | 76.1 | 69.9 | 75.9 |
| OBQA | Open-book science reasoning | 88.7 | 88.7 | 87.7 | 91.0 | 85.0 | 79.3 |
Headline
| Benchmark | Xevn | JevK5 | Plumb | Decider | Mica | Tev1 |
|---|---|---|---|---|---|---|
| MMLU | 83.2 | 79.7 | 78.8 | 80.0 | 77.3 | 74.2 |
| ARC | 94.8 | 94.9 | 87.7 | 95.6 | 97.0 | 94.6 |
| SciQ | 94.5 | 94.2 | 88.7 | 94.1 | 95.5 | 94.7 |
| PIQA | 80.8 | 84.6 | 83.0 | 87.2 | 81.5 | 79.7 |
| Social IQa | 79.6 | 82.4 | 78.1 | 75.8 | 67.3 | 77.6 |
| OBQA | 84.9 | 86.1 | 78.6 | 89.6 | 86.9 | 83.2 |
Speed
Latency of a single request over HTTP, bf16, Apple M4 Max, 3,000 requests. MLX runtime, one question per request.
| Input length | p50 | p95 |
|---|---|---|
| up to 64 tokens | 56 ms | 64 ms |
| 65 to 128 tokens | 88 ms | 103 ms |
| 129 to 256 tokens | 156 ms | 188 ms |
Model files
| Format | Precision | Size | Speed (p50) | Repository |
|---|---|---|---|---|
| Transformers | 16-bit | 9.3 GB | **** | Xevn-4B |
| MLX | 16-bit | 8.4 GB | 88 ms | Xevn-4B-MLX-bf16 |
| MLX | 8-bit | 4.5 GB | 83 ms | Xevn-4B-MLX-8bit |
| MLX | 6-bit | 3.4 GB | 82 ms | Xevn-4B-MLX-6bit |
| MLX | 5-bit | 2.9 GB | 80 ms | Xevn-4B-MLX-5bit |
| MLX | 4-bit | 2.4 GB | 78 ms | Xevn-4B-MLX-4bit |
| MLX | 3-bit | 1.8 GB | 77 ms | Xevn-4B-MLX-3bit |
| GGUF | BF16 | 8.67 GB | Xevn-4B-GGUF | |
| GGUF | Q8_0 | 4.61 GB | Xevn-4B-GGUF | |
| GGUF | Q6_K | 3.56 GB | Xevn-4B-GGUF | |
| GGUF | Q5_K_M | 3.16 GB | Xevn-4B-GGUF | |
| GGUF | Q4_K_M | 2.78 GB | Xevn-4B-GGUF |
Speed is the MLX p50 over an equal mix of the three input lengths in the Speed table, measured in one session on an Apple M4 Max. On every benchmark, MLX 8-bit to 5-bit stay within 2 points of 16-bit accuracy and 4-bit within 3 points. 3-bit loses 7 to 21 points and is provided for experimentation. The Transformers weights keep the original multimodal layout (9.3 GB); the helper uses the text model only.
MLX accuracy and Headline by precision
Accuracy (%)
| Benchmark | 16-bit | 8-bit | 6-bit | 5-bit | 4-bit | 3-bit |
|---|---|---|---|---|---|---|
| KoBEST | 89.7 | 89.7 | 89.6 | 89.5 | 87.4 | 79.7 |
| KorMedMCQA | 69.4 | 69.1 | 69.6 | 68.5 | 66.4 | 50.8 |
| HAE-RAE | 58.3 | 58.3 | 56.5 | 57.5 | 56.3 | 40.2 |
| Belebele | 89.0 | 88.8 | 89.0 | 88.7 | 87.8 | 80.8 |
| KMMLU | 56.3 | 56.1 | 55.8 | 56.8 | 55.3 | 42.3 |
| CSAT-QA | 68.8 | 68.3 | 67.7 | 69.4 | 66.8 | 48.3 |
| CLIcK | 66.5 | 66.2 | 66.9 | 65.9 | 65.8 | 58.8 |
| KMMLU-1035 | 50.1 | 49.9 | 50.5 | 50.9 | 50.1 | 41.5 |
Headline
| Benchmark | 16-bit | 8-bit | 6-bit | 5-bit | 4-bit | 3-bit |
|---|---|---|---|---|---|---|
| KoBEST | 92.0 | 91.9 | 92.4 | 91.4 | 90.8 | 80.6 |
| KorMedMCQA | 78.7 | 78.7 | 79.0 | 77.8 | 75.5 | 65.9 |
| HAE-RAE | 70.2 | 69.9 | 68.9 | 68.2 | 68.1 | 56.9 |
| Belebele | 90.3 | 90.0 | 89.6 | 89.2 | 89.6 | 82.8 |
| KMMLU | 68.5 | 68.7 | 68.1 | 69.7 | 69.1 | 55.8 |
| CSAT-QA | 76.4 | 76.4 | 74.7 | 74.5 | 74.5 | 61.8 |
| CLIcK | 72.5 | 72.2 | 72.6 | 73.1 | 74.5 | 68.0 |
| KMMLU-1035 | 60.1 | 59.9 | 60.8 | 61.3 | 61.1 | 53.4 |
Intended use and limitations
Xevn is built for decisions: classification, multiple choice, yes/no judgments, and rating. It is not a chat or text-generation model. It is tuned for Korean; English input works but is not the focus.
- Xevn returns probabilities over the options you give it. It does not generate text and cannot answer open questions.
- The bundled helpers run one forward pass per question and accept 2 to 26 options and 2 to 10 score levels.
- Speed figures are for MLX on an Apple M4 Max with inputs up to 256 tokens.
Citation
@misc{xevn2026,
  title  = {Xevn-4B: a Korean decision model},
  author = {Nhahan},
  year   = {2026},
  url    = {https://huggingface.co/quevirus/Xevn-4B}
}
License
Apache 2.0. Built on Qwen3.5-4B.
- Downloads last month
- 105
Model tree for quevirus/Xevn-4B
Base model
Qwen/Qwen3.5-4B-Base